Ali Torabi
PhD Student in Computer Science
Spatial & Relational Reasoning in Vision-Language Models, 3D Scene Understanding, and Explainable AI

PhD Student in Computer Science
Spatial & Relational Reasoning in Vision-Language Models, 3D Scene Understanding, and Explainable AI
I am a PhD student in Computer Science at the University of Wyoming, working under the supervision of Dr. Yaqoob Majeed. My research focuses on developing novel techniques in Explainable AI (XAI) for Computer Vision, particularly in Weakly Supervised Semantic Segmentation (WSSS).
I'm passionate about bridging the gap between theoretical research and practical applications in deep learning. My work involves developing influence-guided Class Activation Mapping (CAM) techniques with instance-level refinement and GPU-optimized scaling for large-scale datasets such as PASCAL VOC and COCO.
My current work focuses on reasoning in LLMs and Vision-Language Models, especially relational reasoning and counting of 3D objects in complex scenes, across single images, multi-view 3D data, and video. I build controllable 3D benchmarks with exact ground truth, 3D scene-graph reasoners that lift depth and open-vocabulary perception into metric space, and R1-style reinforcement learning (GRPO with verifiable rewards) to improve the spatial reasoning of VLMs such as Qwen2.5-VL.
With a strong background in software engineering and industrial experience in iOS development with ML integration, I bring both academic rigor and practical expertise to my research. I have published in top venues including Springer Neural Processing Letters and have papers under review in leading journals.
PhD in Computer Science
University of Wyoming
Spatial Reasoning in VLMs
Explainable AI
NSF ART Grant
Multiple Publications
Counting and relational reasoning about 3D objects in complex scenes, from single images to multi-view 3D data and video.
Lifting depth and open-vocabulary perception into metric 3D scene graphs, and GRPO with verifiable rewards to teach VLMs to reason in 3D.
Developing novel CAM-based techniques with influence functions for improved segmentation with weak annotations.
Creating interpretable deep learning models with explanation methods to improve neural network predictions.
Exploring transformer architectures for computer vision tasks and multi-modal learning applications.
Optimizing model training with CUDA, mixed-precision training, and multi-GPU parallelism for large-scale datasets.
Counting and relational reasoning in 3D scenes with Vision-Language Models
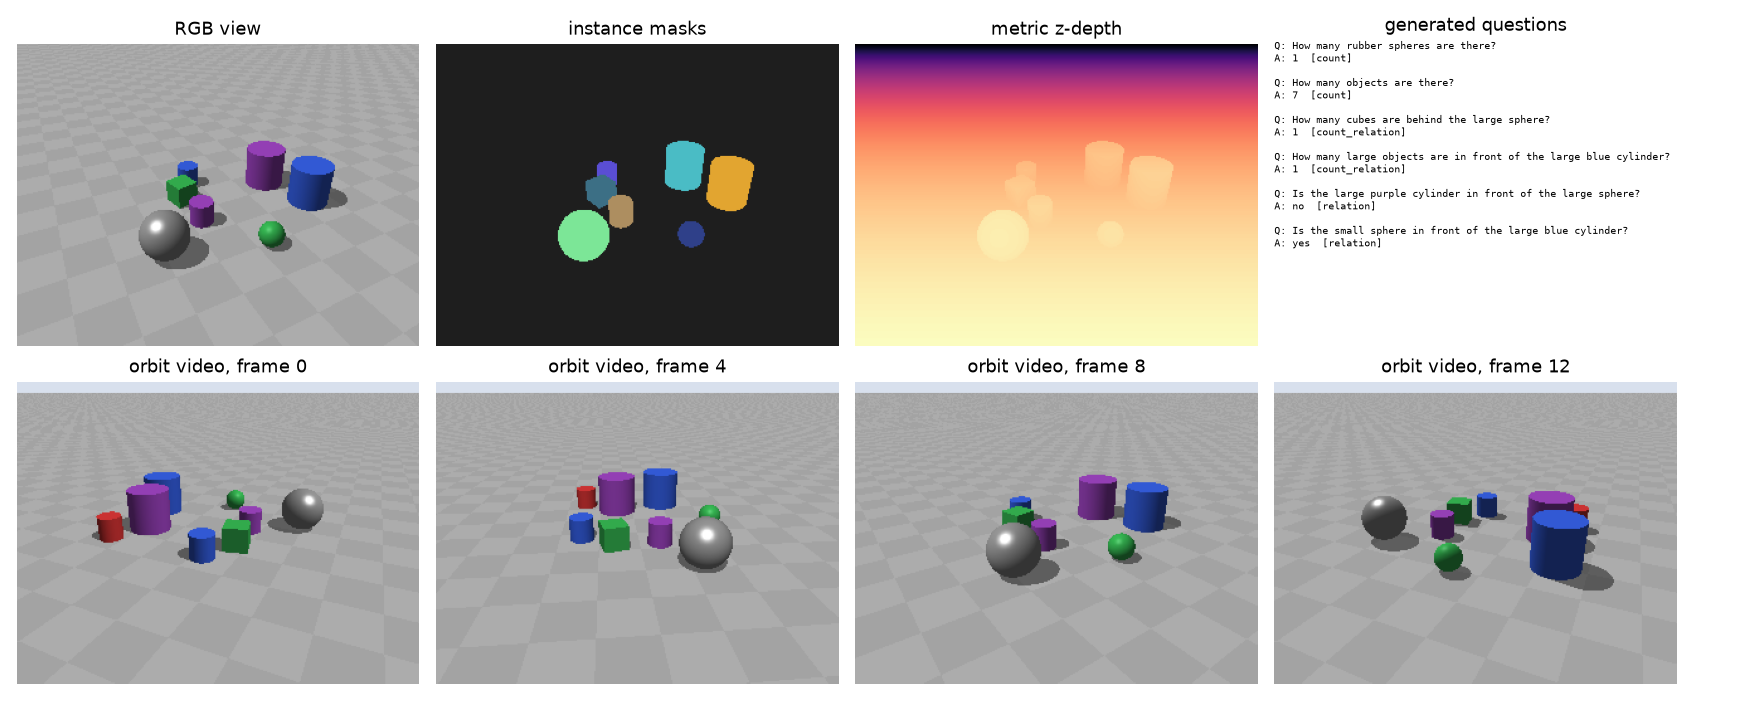
Procedural 3D scenes with exact ground truth (depth, instance masks, camera poses, orbit videos) and occlusion-aware questions on counting, viewer-centric relations, metric distance and egocentric direction for evaluating VLMs.
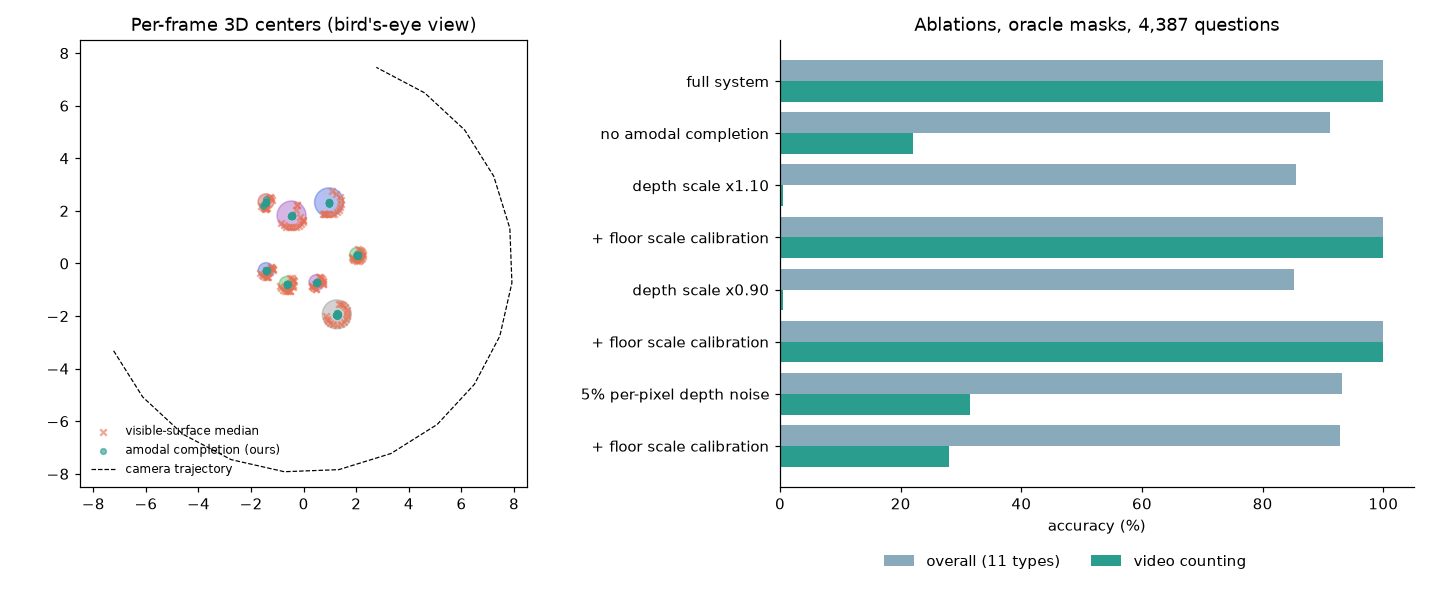
Lifts open-vocabulary detection, SAM masks and metric depth into a 3D scene graph with amodal object completion and multi-view fusion, then answers counting and relational questions with a neuro-symbolic solver or graph-prompted LLM.
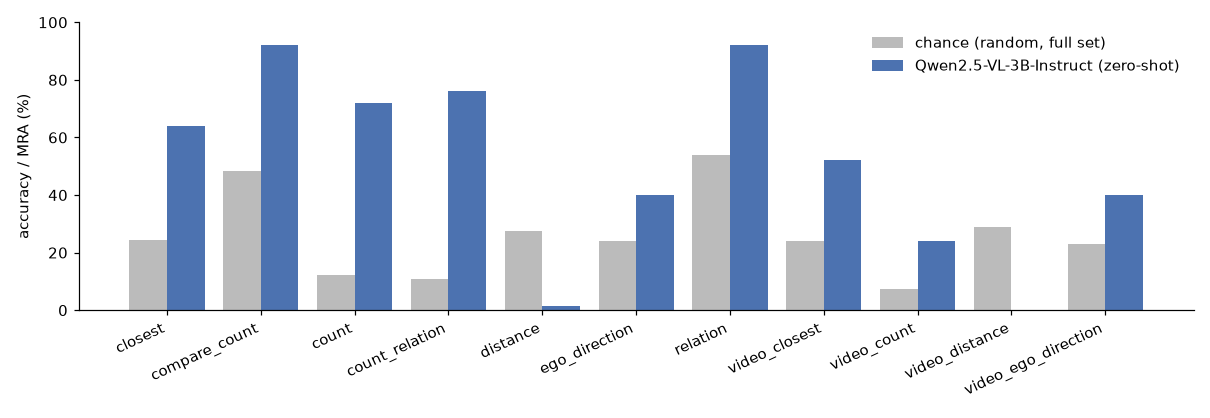
R1-style GRPO with verifiable rewards (format, exact-count, MRA for metric answers) to improve counting and spatial reasoning of Qwen2.5-VL on images and multi-frame video, built on TRL with LoRA, Dr. GRPO and DAPO objectives.
Computer Vision & Vision-Language Model Projects
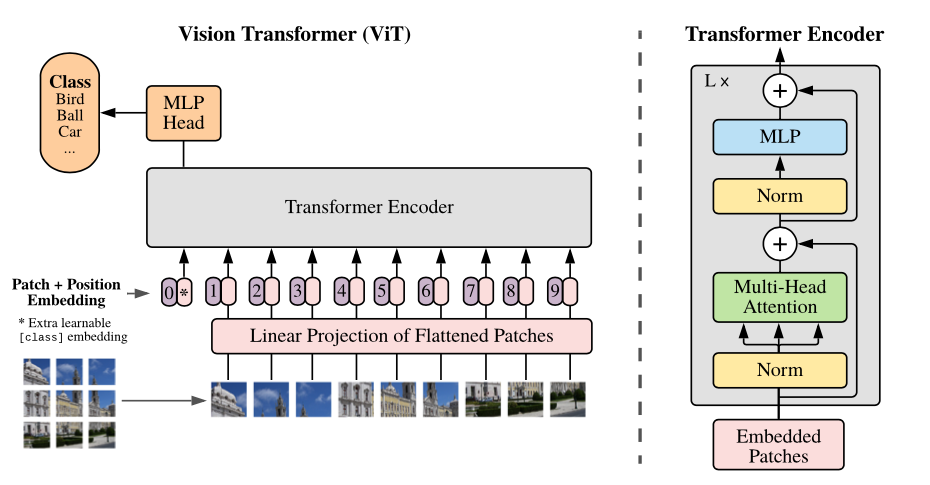
Complete PyTorch implementation of ViT with attention visualization and transfer learning capabilities.
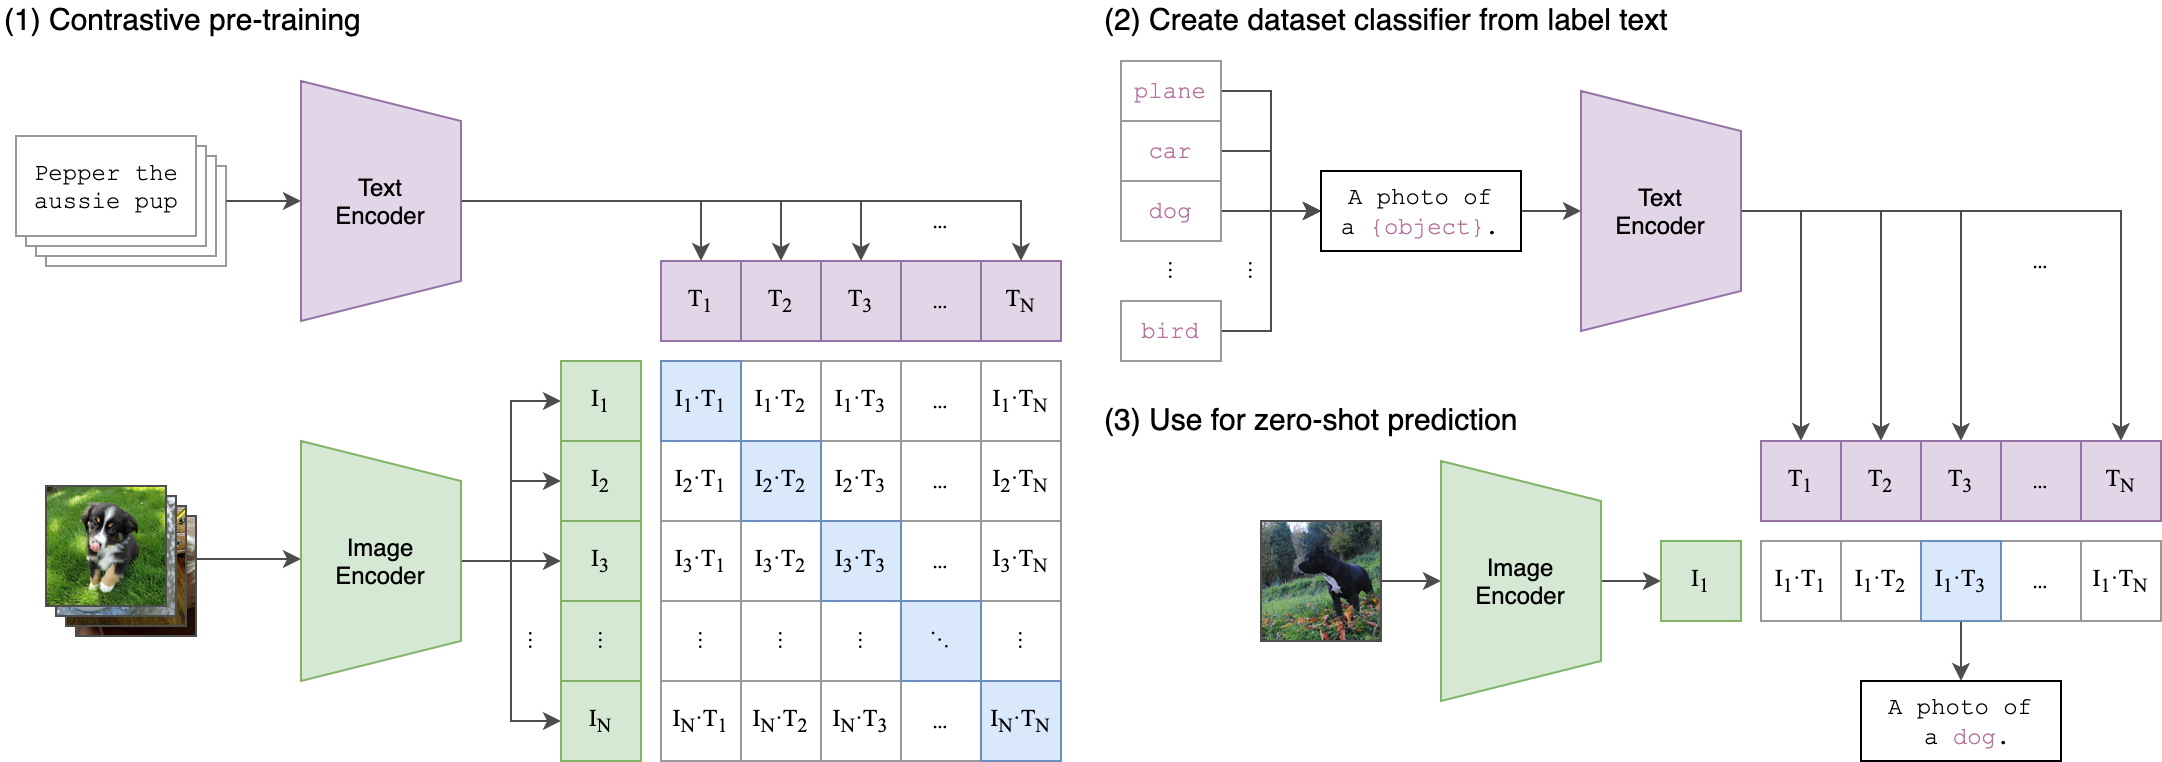
Semantic image search using OpenAI CLIP for natural language queries with FAISS integration.

Automatic caption generation using BLIP, BLIP-2, and GIT vision-language models.
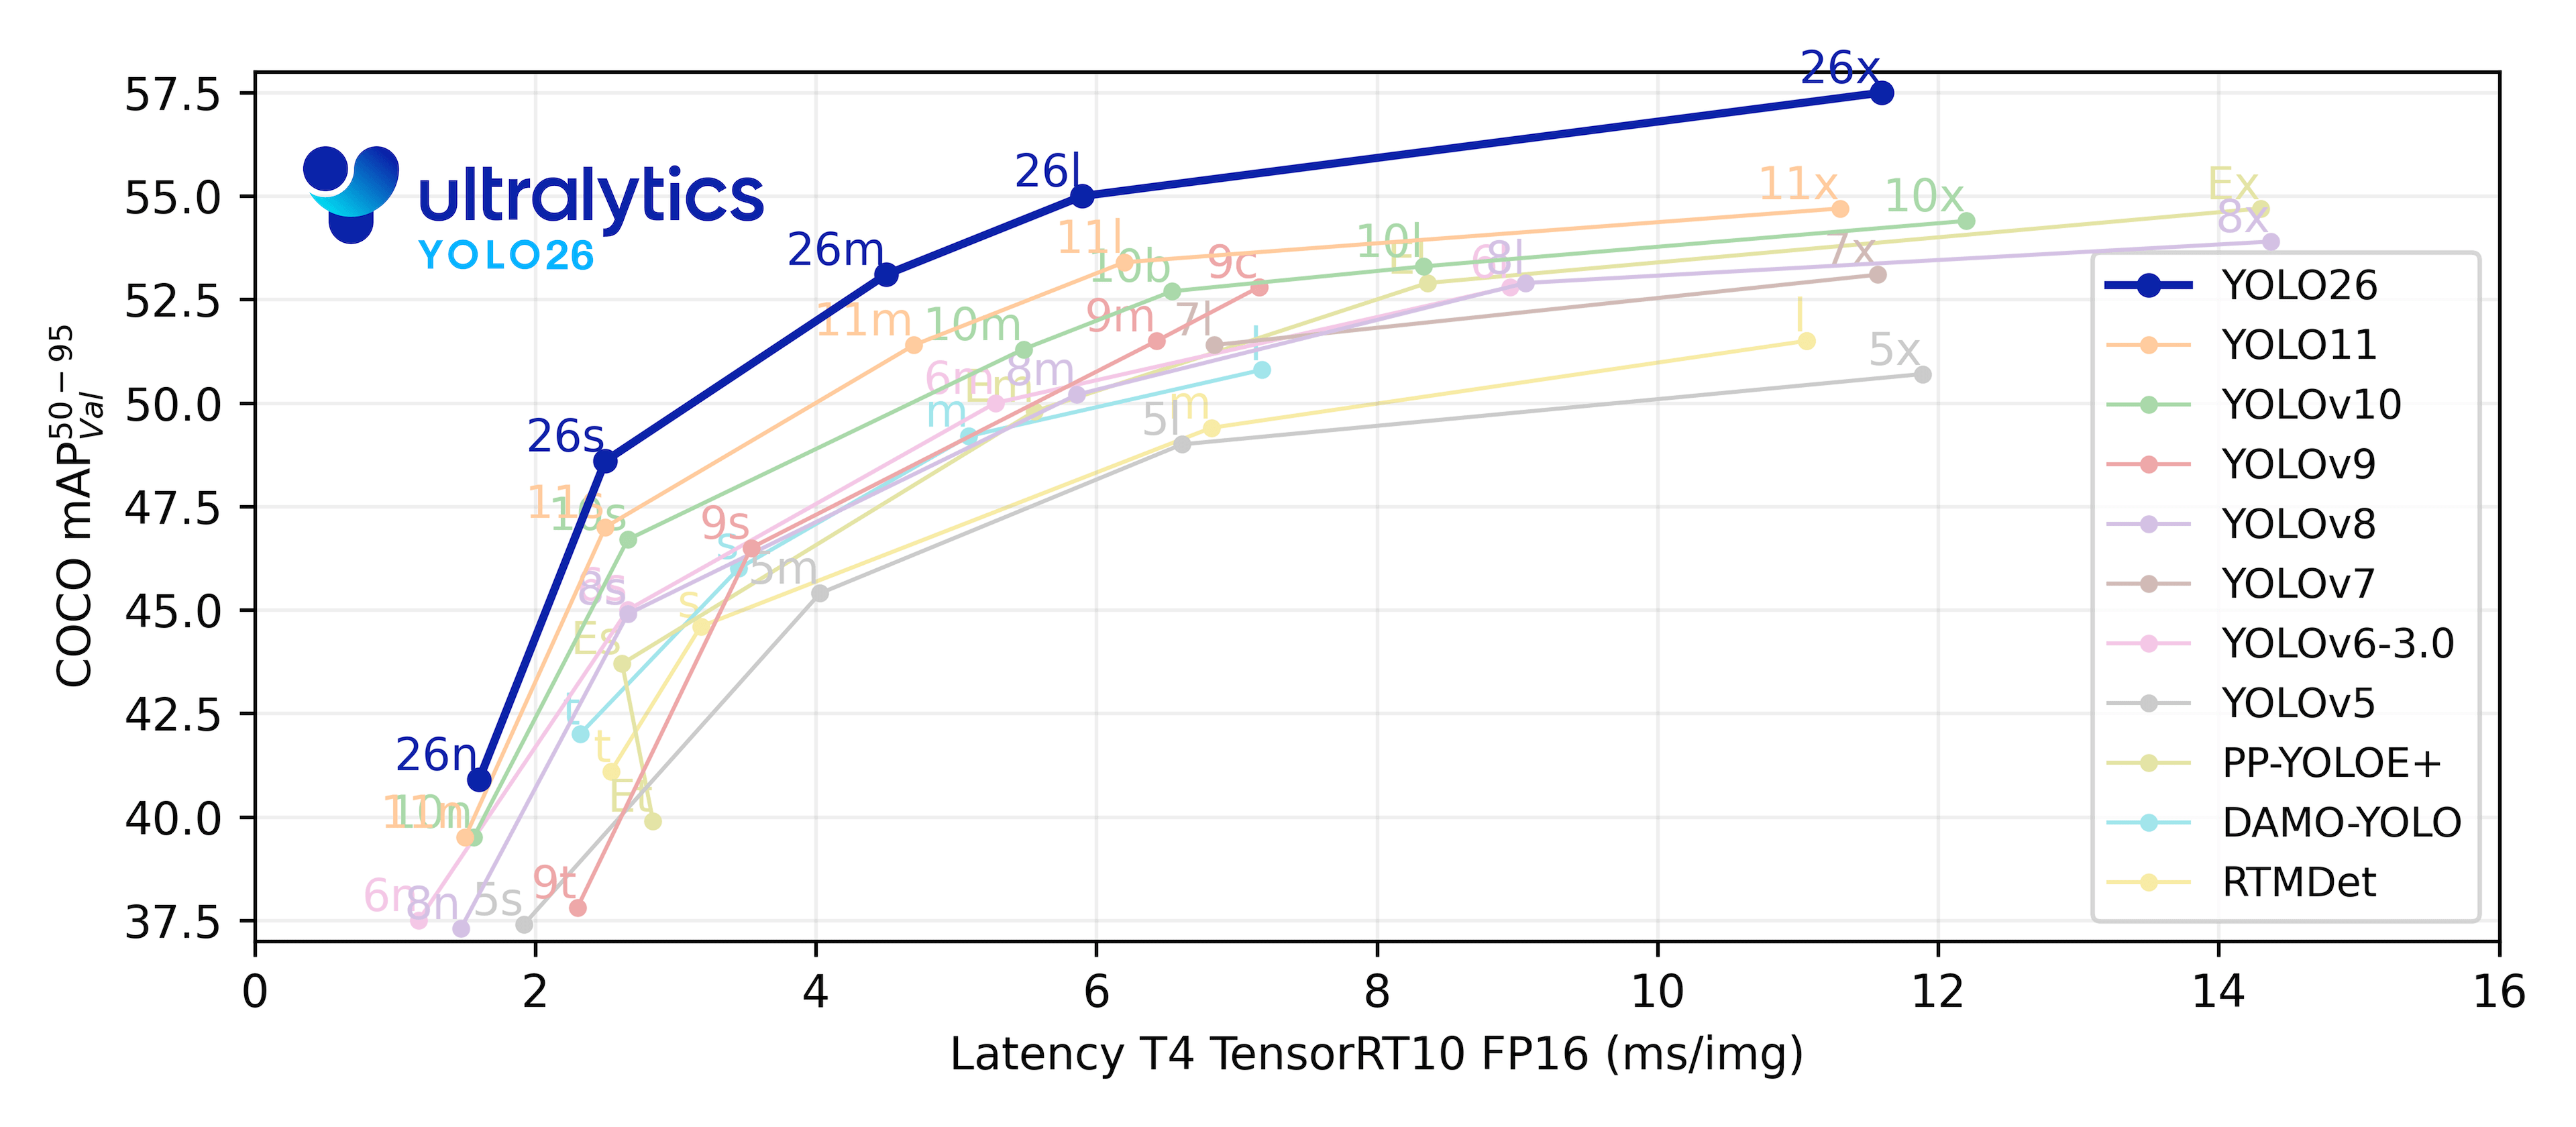
Real-time object detection with YOLOv8 supporting 80+ classes with video processing.

Pixel-level classification using DeepLabV3 with 21-class PASCAL VOC segmentation.

Answer questions about images using BLIP-2 and multi-modal reasoning.
arXiv:2509.12496, 2025
Research Square (Preprint), July 2025
Springer, Neural Processing Letters, 2023
International Journal of Bio-Inspired Computation
Online Social Networks and Media
Conducting research on Explainable AI in Deep Learning and Image Recognition. Developing influence-guided CAM techniques for Weakly Supervised Semantic Segmentation with GPU-optimized scaling on PASCAL VOC and COCO datasets.
Designed and implemented a web-based 3D STL visualization platform with interactive cross-sectioning and advanced rendering using Three.js and WebGL for F3DT commercialization project.
Served as TA for five consecutive semesters, providing mentorship in algorithmic problem solving and complexity analysis.
Developed iOS applications with ML integration. Built Deep CNN models for product image recognition and implemented ML functionality across iOS devices including watchOS.
I'm always open to discussing research opportunities, collaborations, or potential positions in Computer Vision and Deep Learning.
+1 (949) 738-3001
University of Wyoming
Laramie, WY, USA